
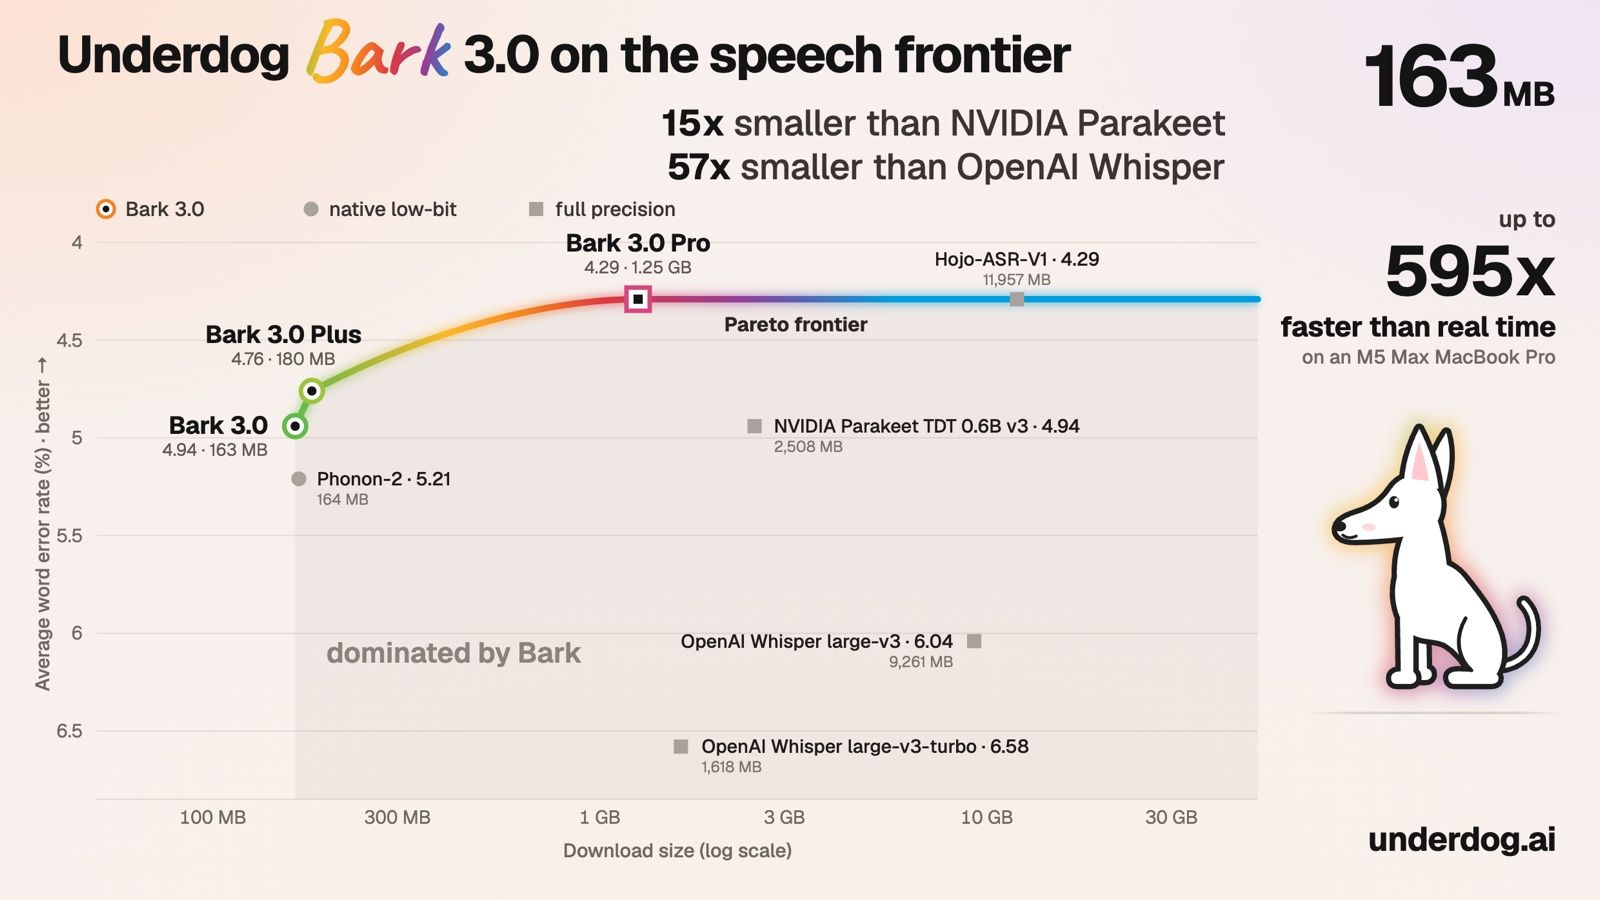
Bark 3.0 is an English speech recognition model in a 163 MB file. It matches NVIDIA's Parakeet TDT 0.6B v3, a 2.5 GB download, and beats Whisper large-v3, which is 57 times bigger. It came out on 15th October 2026.
It is the speech engine of Underdog, a local AI assistant for email, calendar, meeting notes and dictation. The weights are open on Hugging Face under CC-BY-4.0, so you can use them without the app.
| Maker | Conway Research (Underdog), founded 2026 by Sigil Wen |
| Base model | NVIDIA Parakeet TDT 0.6B v3, via Moondream's parakeet-ultra |
| Size | 0.6 billion parameters, 163 MB download |
| Language | English only |
| Accuracy | 4.94% average word error on the 7 Open ASR Leaderboard sets |
| Speed | 41x realtime on an M2 (stock mlx-audio), 595x on an M5 Max inside Underdog |
| Licence | CC-BY-4.0, same as Parakeet |
| Runs on | Apple Silicon (MLX, Core ML), Windows and Linux (PyTorch, CUDA or CPU) |
The Bark 3.0 family
4 variants, 1 trade-off each:
| Model | Download | Word errors | Use |
|---|---|---|---|
| Bark 3.0 Clean | 180 MB | 5.83%* | Drops "um", fillers and false starts |
| Bark 3.0 | 163 MB | 4.94% | Every word, smallest file |
| Bark 3.0 Plus | 180 MB | 4.76% | Every word, fewer mistakes |
| Bark 3.0 Pro | 1.25 GB | 4.29% | Full precision, most accurate |
* Clean scores worse on purpose: the test sets keep every "um", so each one Clean drops counts as an error. Against cleaned transcripts it scores 4.08%, where plain Bark 3.0 scores 16.53%.
Clean is the interesting one for dictation. "Um, I don-, I can't think off my head" comes out as "I can't think off my head". Underdog uses it by default.
Accuracy and size
Scored on the Open ASR Leaderboard English sets: audiobooks, meetings, earnings calls, podcasts, finance calls and parliament speeches. Lower is better.
| Model | Download | Meetings (AMI) | Average |
|---|---|---|---|
| Bark 3.0 Pro | 1,254 MB | 7.16% | 4.29% |
| Bark 3.0 Plus | 180 MB | 7.76% | 4.76% |
| Bark 3.0 | 163 MB | 7.82% | 4.94% |
| Qwen3-ASR-1.7B | 4,699 MB | 8.31% | 4.43% |
| Parakeet TDT 0.6B v3 | 2,508 MB | 9.42% | 4.94% |
| Phonon-2 | 164 MB | 9.32% | 5.21% |
| Whisper large-v3 | 9,261 MB | 13.63% | 6.04% |
| Whisper large-v3-turbo | 1,618 MB | 13.88% | 6.58% |
Meetings are where it shows. Bark 3.0 gets 7.82% of meeting words wrong, Parakeet 9.42%, Whisper large-v3 13.63%.
2 caveats:
- Self-scored. The Bark rows use the leaderboard's scoring code but are not on the leaderboard yet. The other rows are its published numbers, as of 9th October 2026.
- A tie, not a win, against Parakeet. 4.937% against 4.941% at 3 decimals. The real gain is the 15x smaller file.
Its closest rival is Phonon-2 from Fermion Research, same size, same Parakeet parent, 5.21% (see Phonon-2). Bark 3.0 beats it on every count, and the gap is widest on meetings.
For business people
What it does. It turns recorded or live English speech into text on the laptop. No audio goes to a cloud.
Why it matters. Meeting notes and dictation are the 2 places where people send the most sensitive audio to a third party: client calls, deal terms, HR conversations. A 163 MB model that is as accurate as the big ones removes the reason to do that. It also runs offline and costs nothing per minute.
Where it fits.
- Dictation into any app.
- Meeting transcripts, followed by a local summary.
- Batch transcription of recordings, interviews and calls.
Cost. The model is free, including for commercial use, with attribution (CC-BY-4.0). The Underdog app is in invite-only beta, free for now. Its founder plans to earn a small share of purchases made through the assistant, not to charge per request or sell ads.
Limits.
- English only. Parakeet v3, its parent, speaks 25 European languages. For other languages Underdog falls back to Whisper large-v3-turbo.
- No speaker names and no word timings yet. Meeting notes separate you from the call, not each person on it.
- Underdog's custom words list (names, jargon) doesn't work with Bark 3.0 yet, only with Bark 1.0.
- The benchmark numbers come from the maker.
When to choose it. English-only teams on Macs who want the best accuracy for the smallest footprint. For multilingual work, stay on Parakeet v3 or Whisper.
For technical people
Architecture. Bark is a fine-tune of Parakeet TDT 0.6B v3: a FastConformer encoder with a Token-and-Duration Transducer (TDT) decoder. It came through Moondream's parakeet-ultra. The tokenizer, punctuation, casing and numeral output are Parakeet's.
The file format. Weights ship as a single packed model.bark. The loader depends on constriction, an entropy-coding library, so the file packs low-bit weights further on top of quantization. On first run, the weights unpack into an MLX folder and get cached. The unpacked weights are bit-identical to the ones the benchmarks measured.
Runtimes.
| Runtime | Platform | Notes |
|---|---|---|
bark_mlx.py |
Apple Silicon | Stock mlx-audio, about 41x realtime on an M2 |
bark_loader.py |
CUDA, CPU, MPS | PyTorch, expands weights to FP32 in memory |
| Core ML GPU or ANE | macOS 15+, iOS 18+ | FP16 encoder, int8 TDT decoder on CPU, 8 s and 15 s windows |
| Native Swift + MLX | Underdog app | No Python, unpacks in about 2 s, checks SHA-256 on download |
Run it on a Mac:
pip install huggingface_hub==2.2.0
hf download ConwayResearch/Underdog-Bark-3.0 --local-dir bark-3.0 \
  --include "model.bark" --include "bark_mlx.py" --include "mlx/*" --include "NOTICE"
cd bark-3.0
pip install mlx==0.32.2 mlx-audio==0.5.3 constriction==0.5.0 numpy==2.4.6 soundfile==0.14.0 soxr==1.1.0
python bark_mlx.py recording.wav
From Python, with the PyTorch loader:
from bark_loader import load_model, transcribe
import soundfile as sf

model = load_model("model.bark", device="mps")  # or "cuda", "cpu"
wave, sr = sf.read("recording.wav", dtype="float32", always_2d=True)
print(transcribe(model, wave.mean(1), sr))
Gotchas.
⚠️ WARNING: stock mlx-audio transcribes a file in 1 pass, so memory grows with length. A 10-minute file peaked at about 15 GB on a 16 GB M2. Split long recordings into chunks of a few minutes, cut at pauses.
transcribeadds 0.25 s of silence before the audio. The published numbers use that setting, so keep it.- The download size is not the memory size. The PyTorch path expands to FP32.
- The Core ML packages are validated on short clips only, and first-use compilation can take minutes. Keep one
Transcriberalive. - The iOS path is documented but not tested on a device yet. For a full Core ML pipeline on iOS, Bark 3.0 Pro runs through FluidAudio, at 1.23 GB.
Underdog, the app on top
Underdog is a local assistant for email, calendar, meeting notes, dictation and errands, on Mac, iPhone and iPad, with Windows in beta. Its reasoning model is Saluki 27B, a 7.89 GB 2-bit build of Qwen3.8-27B. Bark handles the voice: hold fn and talk, or record a meeting.
Conway Research raised its first round in April 2026, led by Andreessen Horowitz, with Khosla Ventures and the Anthology Fund (with Anthropic).
Why it matters for me
My own dictation app, Dictee, runs Parakeet TDT 0.6B v3 on mlx-audio (see Dictee: my own local dictation app). Bark uses the same runtime and the same model family, so a test is cheap: swap the weights and compare on my own recordings.
The catch is language. Dictee has to handle English, French and German, and Bark only does English. A realistic setup: Bark 3.0 Clean for English, Parakeet for the rest. Bark 3.0 Clean could also replace part of my cleanup step for English, since it already drops the fillers.
Further Reading
- Meet Underdog Bark 3.0, the launch post
- Bark 3.0 model card on Hugging Face
- NVIDIA Parakeet TDT 0.6B v3, the base model
- Open ASR Leaderboard
- Meet Underdog Saluki 27B, the reasoning model in Underdog
- Related notes: see Phonon-2, see FluidVoice, see Whisper