Phonon-2 turns English speech into punctuated text, and it does it from a 164 MB file. That's about 15 times smaller than the NVIDIA model it was trained from, with nearly the same accuracy. On a MacBook Air it transcribes an hour of audio in about 20 seconds.
It comes from Fermion Research, a lab that builds very compact models: its Neutrino-1 language models use a ternary format, and Phonon-2 stores its encoder weights in about 2 bits each. The weights are open under CC-BY-4.0.
| Maker | Fermion Research |
| Base model | Distilled from NVIDIA's Parakeet TDT 0.6B v3, its "teacher" |
| Size | 0.6 billion parameters, 164 MB download, 177 MB on disk |
| Language | English only |
| Output | Punctuated, capitalised text from 16 kHz audio |
| Accuracy | 5.21% average word error on the 7 Open ASR Leaderboard sets |
| Licence | CC-BY-4.0 for the weights, Apache 2.0 for the command line |
| Runs on | Apple Silicon (MLX), Linux and Windows CPUs, NVIDIA GPUs |
Accuracy and size
The comparison that matters is accuracy against download size. Lower word error rate (WER) is better.
| Model | Download | Average WER |
|---|---|---|
| NVIDIA Parakeet TDT 0.6B v3, the teacher | 2,508 MB | 4.96% |
| Phonon-2 | 164 MB | 5.21% |
| Moondream Parakeet Redux | 178 MB | 5.69% |
| NVIDIA Canary 180M Flash | 737 MB | 5.69% |
| Mistral Voxtral Mini 4B Realtime | about 8,000 MB | 6.12% |
| Phonon-1, the previous version | 415 MB | 6.56% |
| OpenAI Whisper large-v3-turbo | 1,618 MB | 6.58% |
Fermion's claim: Phonon-2 is the most accurate open model under 900 MB, and every open model that scores better is at least 5.8 times its size. On meeting audio (AMI) and European Parliament speech (VoxPopuli), it even beats its teacher. It's weakest on earnings calls, where it trails the teacher by about 1 point.
Speed
| Where | Times realtime |
|---|---|
| MacBook Air M5, GPU (MLX) | 174x |
| MacBook Air M5, CPU only | 40x |
| Linux, 8 AMD Zen 5 cores | 143x |
| Windows, 8 vCPU | 21x |
| NVIDIA H100, batch of 128 | 6,680x |
On the same MacBook Air, Fermion measured Parakeet TDT 0.6B v3 in FluidAudio's Core ML runtime at 105x, and whisper.cpp large-v3-turbo at 17x.
For business people
What it does: turns recordings and live speech into text, on your own device. No audio leaves the machine, and there's no per-minute bill.
Why it matters: good speech recognition used to mean a cloud API or a model of several gigabytes. At 164 MB, it fits on a laptop, a small server or inside an app download, and still runs faster than realtime on a plain CPU.
Where it fits: dictation, meeting and call transcripts, searchable archives of recorded audio, and subtitles for English content.
Costs: free. The licence allows commercial use with attribution.
The limits:
- English only. The teacher speaks 25 European languages. Phonon-2 doesn't.
- All benchmark and speed numbers are Fermion's own, scored by Fermion with the leaderboard's own code, not published by the leaderboard itself.
- A young lab. Phonon-1 came out on 28th August 2026, and Phonon-2 in late September.
For technical people
- Method: a distillation of Parakeet TDT 0.6B v3 with quantisation-aware training. Every encoder weight is 1 of 5 learned levels, about 2.1 bits per stored weight, with 6-bit tables elsewhere.
- Fast path and exact path: the default decode on the Mac runs at 174x. An exact decode runs at 109x with the same 5.21% WER.
- Packaging: 1 file for every platform, with a Core ML runtime for Apple devices announced but not yet out.
Install and run on Apple Silicon:
pip install fermion-research
pip install mlx mlx-audio mlx-lm soundfile scipy zstandard

fermion transcribe recording.wav --model phonon-2
fermion listen --model phonon-2    # live microphone transcription
fermion serve --model phonon-2     # local OpenAI-compatible transcription endpoint
On Linux or Windows, use Docker:
docker run --rm -v "$PWD":/audio ghcr.io/fermionresearch/phonon-cpu:2.0.2 \
  transcribe /audio/recording.wav --model phonon-2
The serve mode matters most: any tool that already calls OpenAI's transcription API can point at the local endpoint instead.
Detta, the app on top
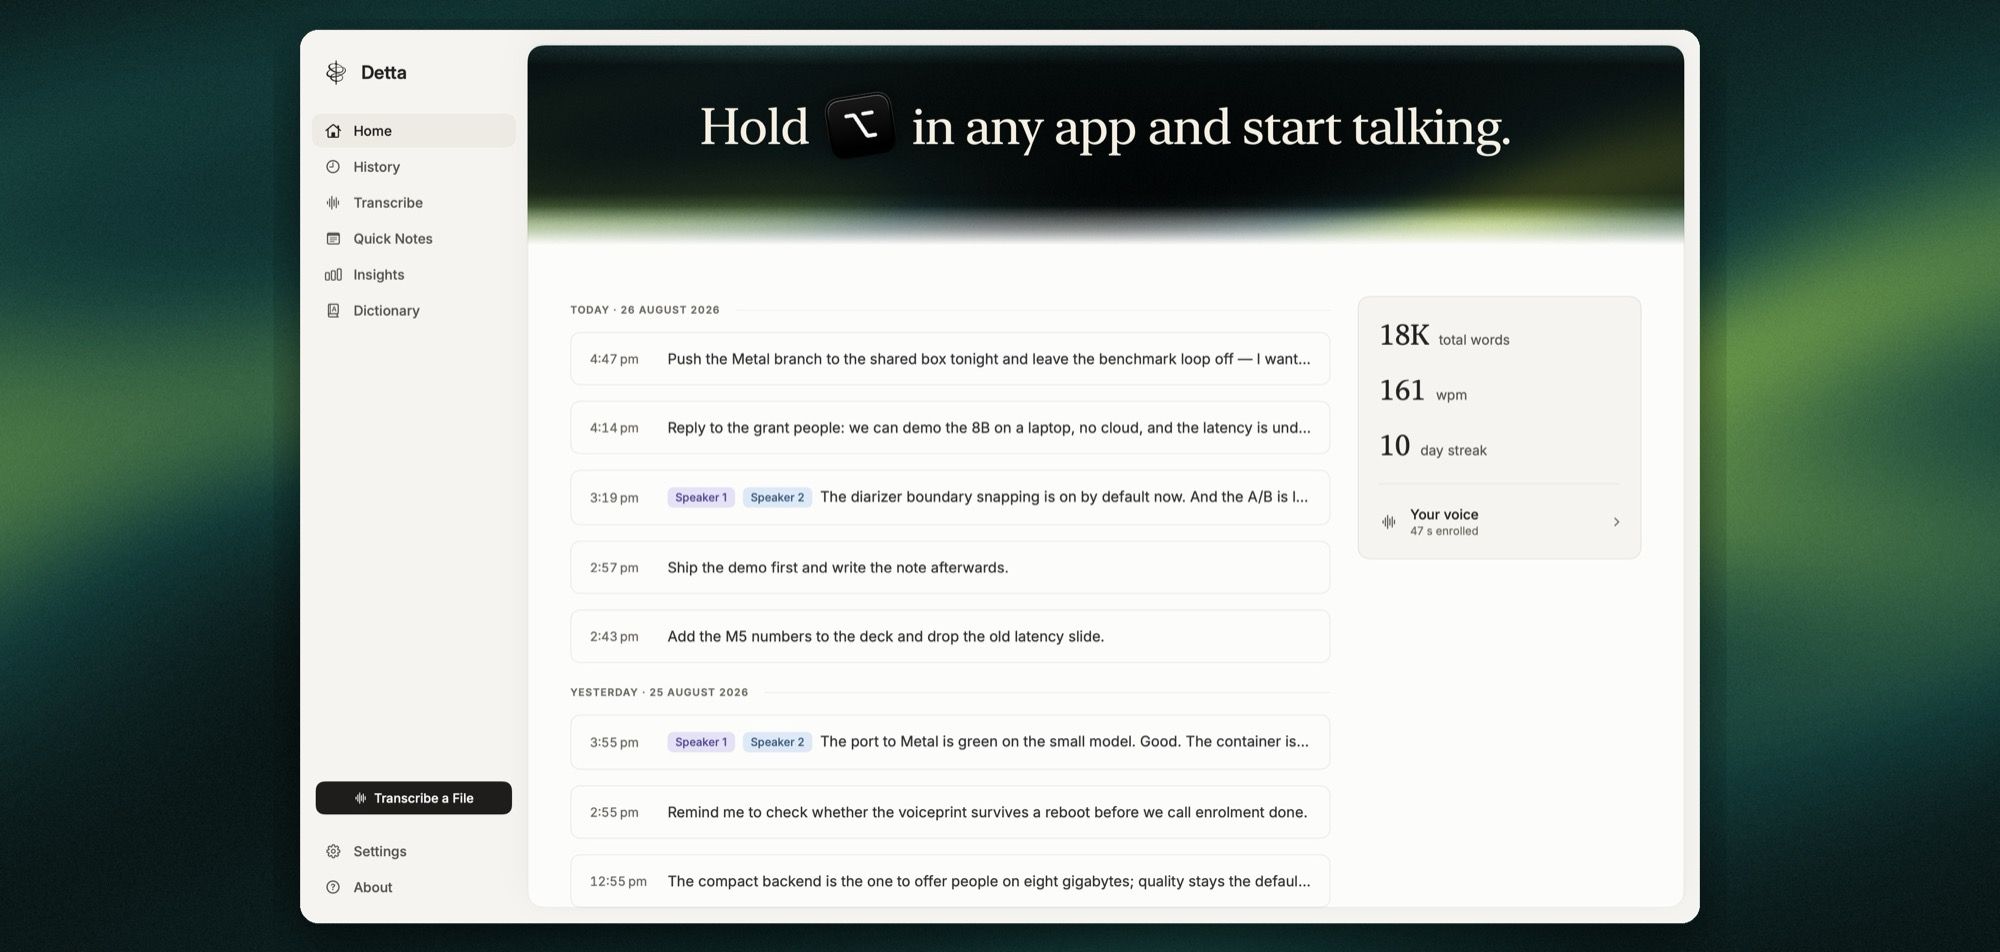
Fermion also makes Detta, a Mac dictation app that runs Phonon-2 on the device: hold a key in any app, speak, and the text appears in the field.
Value
My own dictation app, Dictee, runs the teacher model, Parakeet TDT 0.6B v3, on MLX (see Dictee: my own local dictation app ). Phonon-2 gives nearly the same accuracy at a tenth of the size and a faster runtime. The catch is language: I dictate in English, French and German, and Parakeet covers all 3. Phonon-2 would only replace it for English.
Where it fits for me today is batch work in English: call recordings, webinars and meeting audio, where 174x realtime turns an hour into 20 seconds on the laptop. The fermion serve endpoint makes it a drop-in test for any of my scripts that call a transcription API.
Further Reading